Thoughts on AI, machine learning, technology, and life.
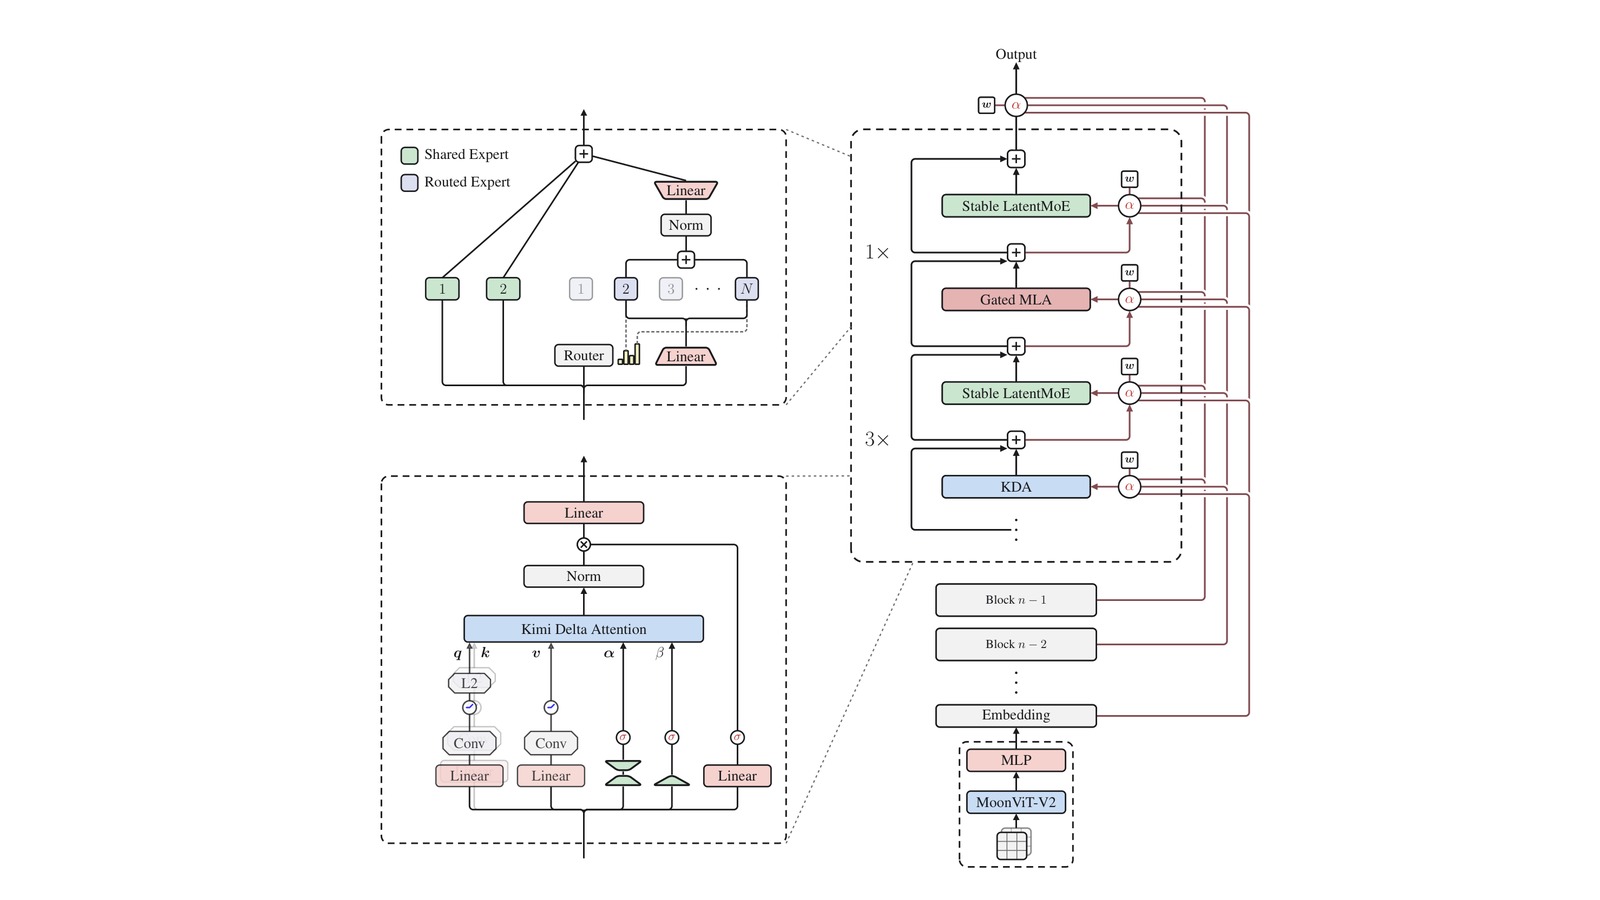
A deep read of the Kimi K3 technical report: a 2.8T parameter open MoE with 104B activated parameters, hybrid KDA attention, Attention Residuals, Stable LatentMoE, and …
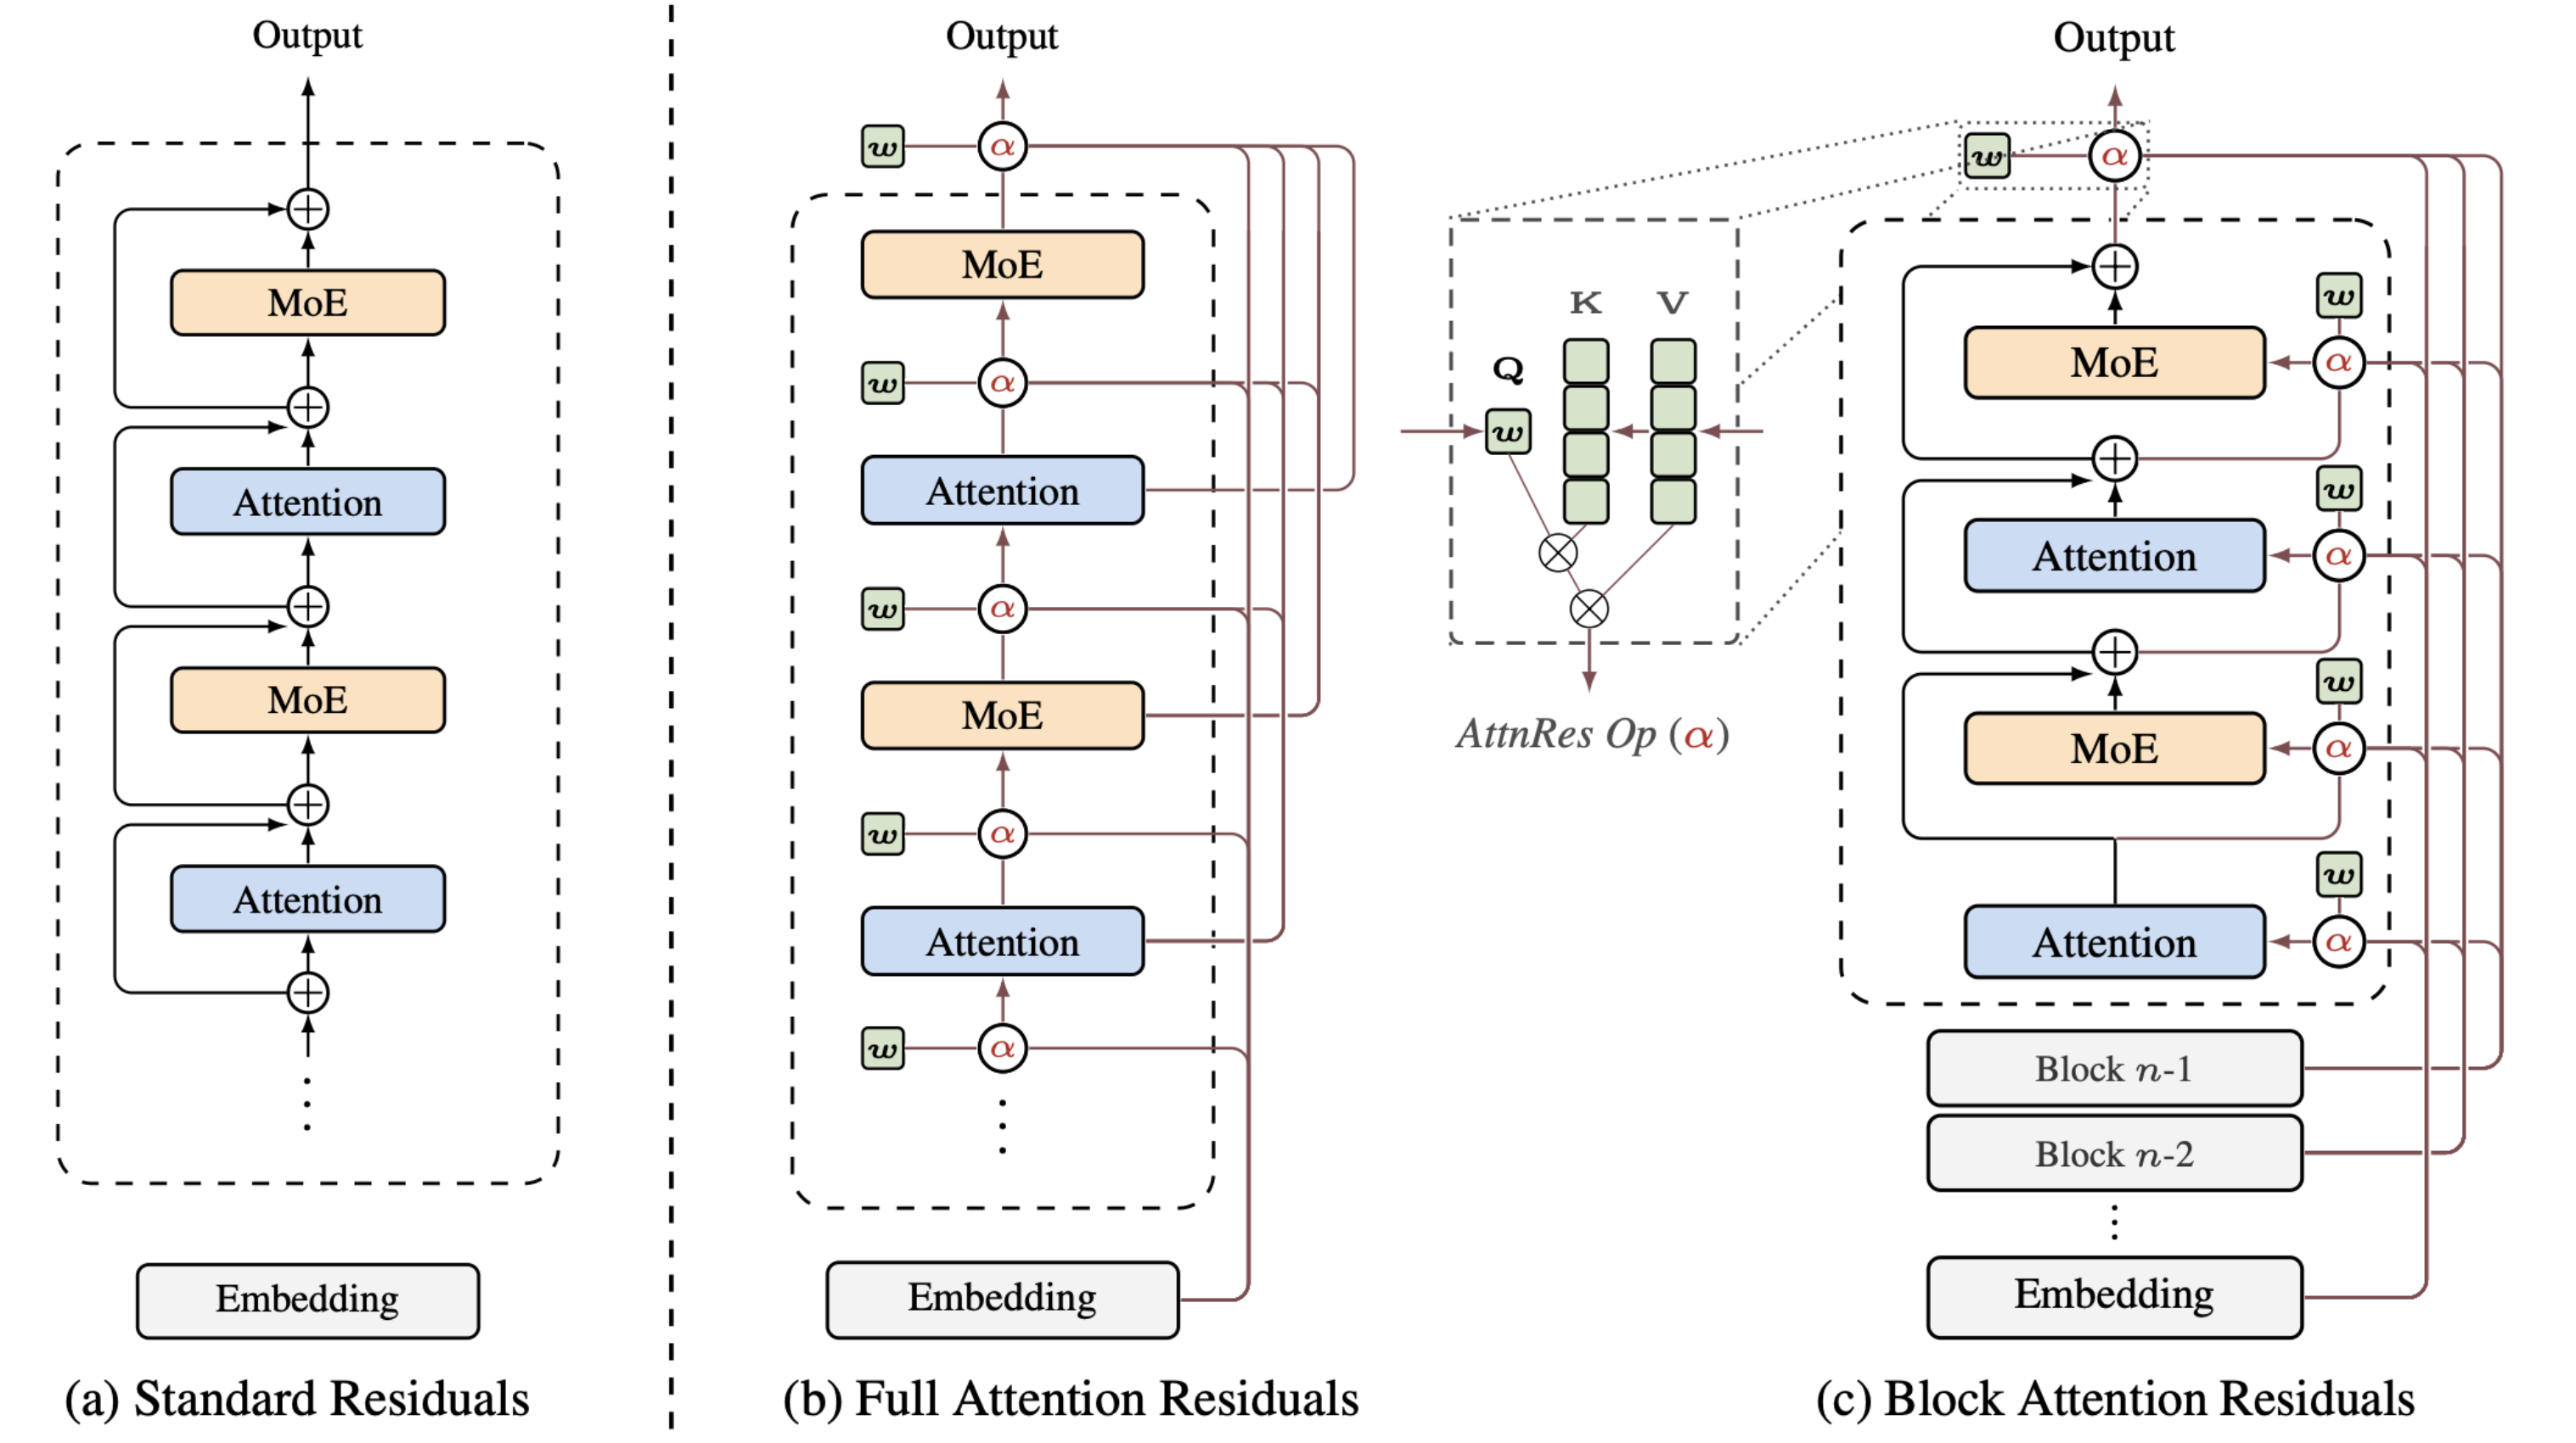
Kimi's Attention Residuals paper proposes replacing fixed residual connections with learned softmax attention over depth, a simple but powerful idea that yields 1.25x …
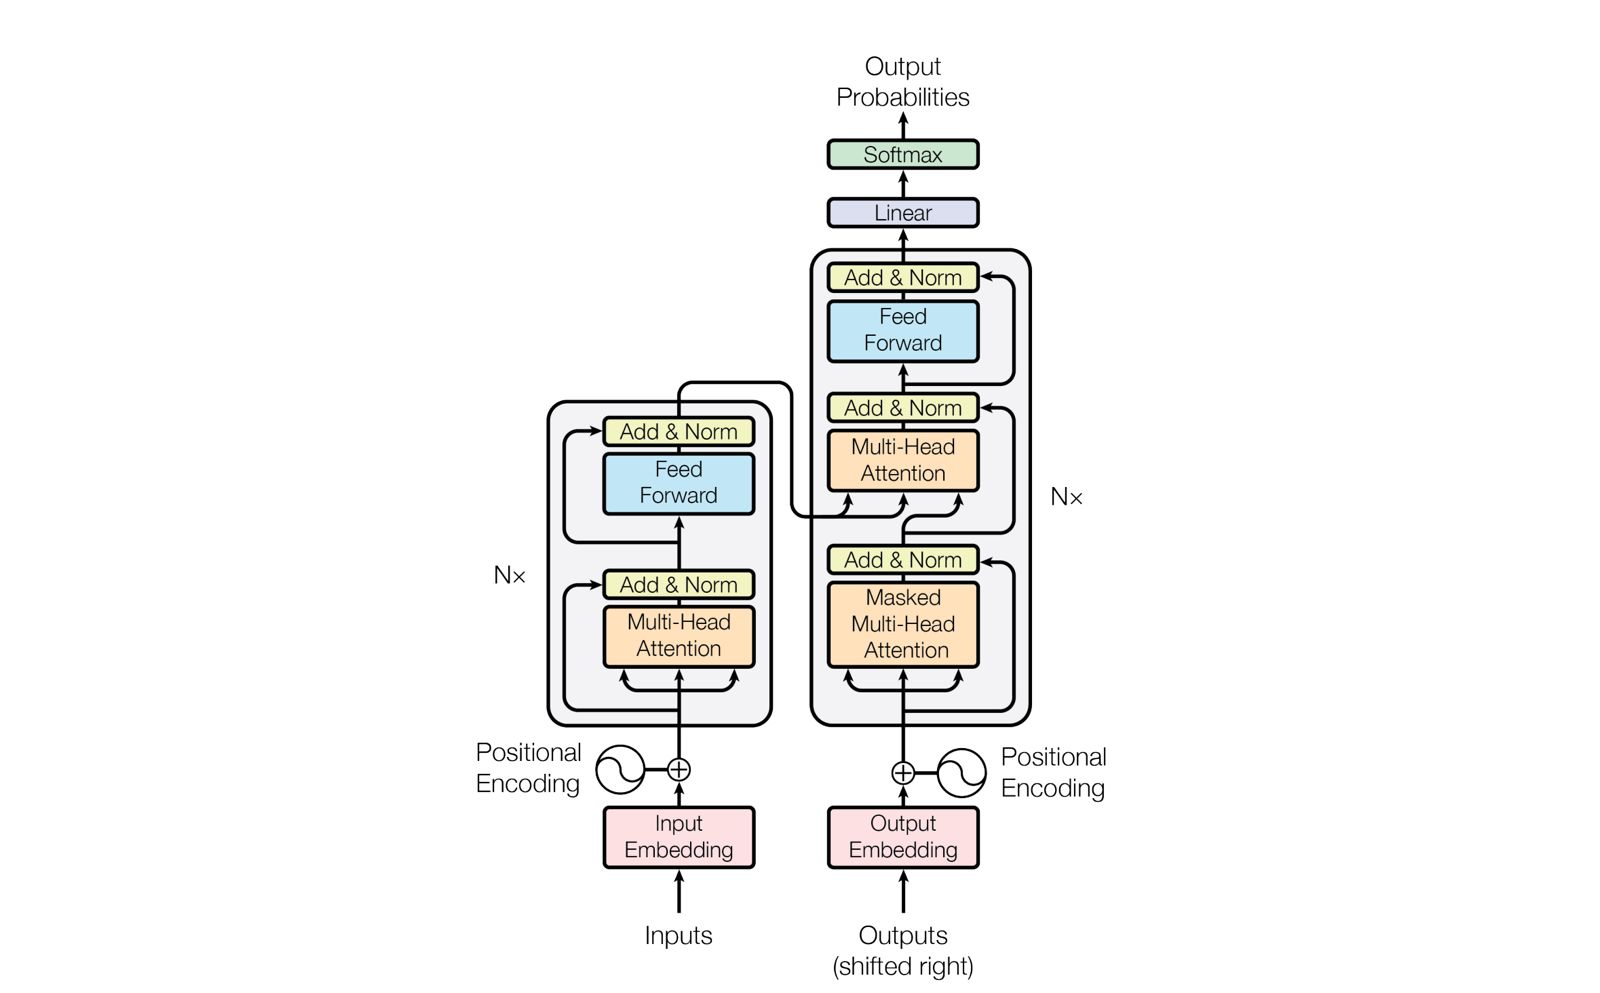
A deep dive comparing standard softmax attention, linear attention, and Flash Attention: their math, complexity, trade-offs, and when to use each.
Google DeepMind unveils Gemini 3 Pro, their most intelligent model to date, outperforming GPT-5.1 and Claude 4.5 across key benchmarks with breakthrough multimodal …
An in-depth analysis of DeepSeek-R1's groundbreaking Nature publication: achieving GPT-4 level performance with pure reinforcement learning at just $294K training cost
Studies from OpenAI and Anthropic reveal differences in how users interact with ChatGPT and Claude, suggesting complementary rather than competing AI ecosystems.
ML/AI Engineer & Data Scientist sharing insights on autonomous AI agents, LLM deployment, and enterprise ML systems